Artificial intelligence systems used to grade undergraduate essays generally award higher marks than human markers and show substantial disagreement with human judgement on individual pieces of work, researchers report.
Key findings from the trial
The research, published in the journal Assessment & Evaluation in Higher Education, uploaded 50 undergraduate bioscience essays into two versions of ChatGPT and asked the models to mark work against seven assessment criteria under four different prompting approaches. The authors concluded that large language models (LLMs) tested "do not reliably reproduce human judgement in the marking of extended written work".
"At present, GenAI is unable to reliably assign a mark to a subjective piece of written work comparable to that of humans – even with extensive training," said report co-author William Kay, senior lecturer in statistics (teaching and scholarship) at Cardiff University.
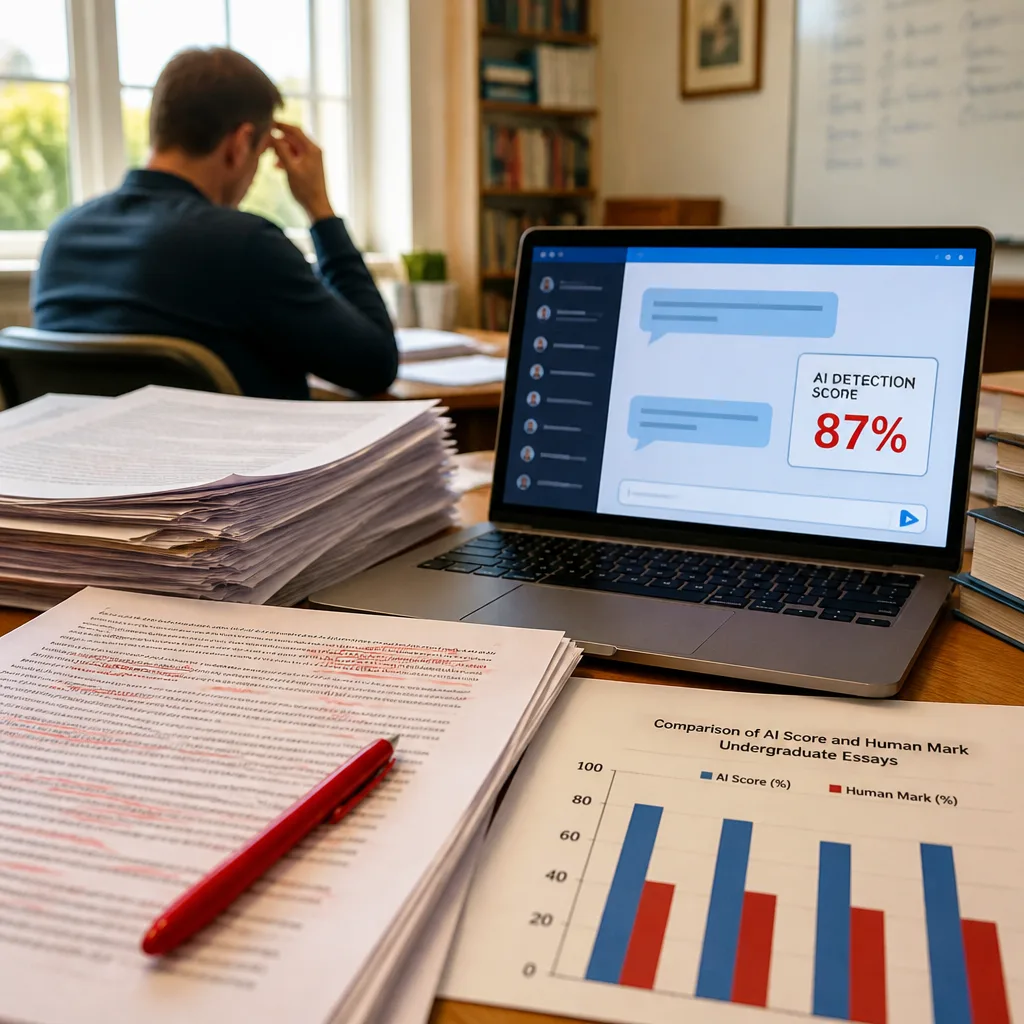
While the overall average marks from the AI were, in some cases, broadly similar to human averages, the picture for individual essays and specific assessment criteria was markedly different. The models frequently returned higher marks than human markers in all but one of the experimental conditions, and the variance between AI and human marks could be substantial.
Where the differences were clearest
The study highlights systematic distortions in how the AI treated essays at different quality levels:
- Lower-scoring essays were often granted inflated marks by the AI.
- Higher-scoring essays sometimes received lower marks from the models than from human markers.
- Mid-range essays showed the closest alignment between AI and human marking.
The researchers also found that the LLMs were relatively consistent when presented repeatedly with the same essay and prompt, yet varied considerably in their marks across essays of differing standards. This meant that while composite overall scores could appear acceptable on average, discrepancies for individual criteria and specific essays were "considerable", reflecting the aggregating effect of a composite mark.
| Parameter | Study result |
|---|---|
| Number of essays tested | 50 |
| Maximum score per essay | 100 |
| Largest single difference reported | 40 marks |
Implications for universities and assessment policy
The report arrives at a time when institutions under pressure from heavy marking workloads are exploring automated or AI-assisted methods to support assessment. Proponents argue that such systems could relieve academics and speed up feedback, but the study cautions against treating generative AI as a reliable substitute for human judgement on subjective, extended written tasks.
Potential consequences include risks to fairness and validity: if weaker students receive inflated marks while stronger students see their work downgraded, the distribution of grades could be distorted. That would have knock-on effects for decisions that depend on accurate assessment, from degree classifications to selection for postgraduate programmes and employability evaluations.
The authors note also that different prompting approaches and versions of the model produced variable outcomes, adding an extra layer of unpredictability and stressing the difficulty of standardising AI marking across institutions or modules.
What this means in the classroom
For lecturers and assessment designers, the findings underline the importance of careful validation before adopting AI marking at scale. Possible interim approaches include using AI to support formative feedback while keeping summative judgement with human markers, employing AI only for objective elements of assessment, or using it as a second-reader tool subject to human moderation.
As universities weigh efficiency gains against the pedagogical and fairness risks, regulators and quality bodies will need evidence-based guidance. The study does not rule out future improvements in AI marking, but it emphasises that current generation systems are "inadequate predictors of the human mark awarded to essays" and should be used with caution.
Policymakers, academic leaders and students alike must now consider where AI can genuinely support teaching and learning — and where human judgement remains essential.